Forward a voice message, interview, podcast or video with speech — Flowmark returns the text to the same chat. With timestamps, speakers and paragraphs, without copying the file into a separate service.
Promo access unlocks every Flowmark tool for 30 days. Right inside Telegram and MAX.
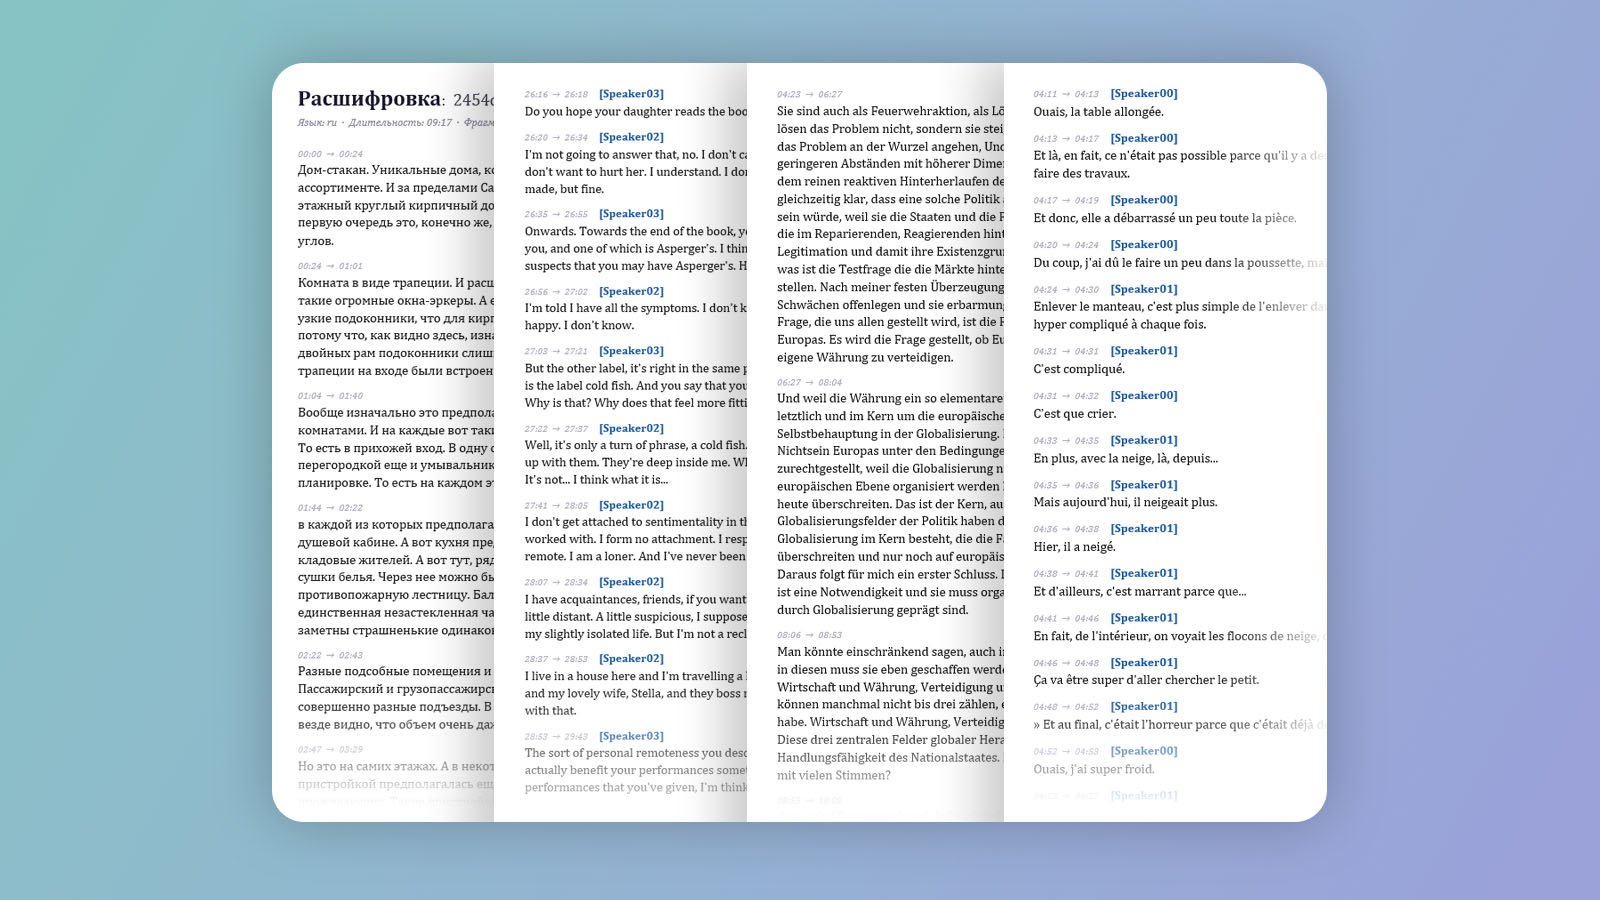
Flowmark earns its keep when the recording is real work: an interview, a podcast, a video with speech. And here transcription isn't a separate service but one of the actions on a file. A video can be transcribed to text, and then, in the same bot, you can bleep out profanity, compress it for publishing or add a logo — without shuttling the file between services.
Before you start, you choose how the result is put together — instead of getting one solid wall of text.
Diarization splits the lines by speaker — handy for interviews, calls and round-tables.
Each fragment is tagged with its time — easy to find the right moment in the original recording.
Flowing text for reading and publishing — or line by line for proofing and edits.
You can take the result in the format you need: plain text (TXT), a formatted DOCX or SRT — subtitles for video and editing. And if you want a different layout afterwards — switch to paragraphs, add or remove timestamps — there's no need to re-upload the recording and wait for a new transcription: a formatting button sits right next to the finished result, and the bot re-formats the already-recognized text to the new settings.
The language of the recording can be set explicitly — it improves accuracy on mixed-language recordings and strong accents. And for recordings with background music there is a dedicated mode: the voice is separated from the instrumental, and recognition runs on the clean vocal track — more about transcribing recordings with music.
A transcription can be stopped while it runs — there is a cancel button next to the progress. The finished text comes back as a reply to that very message with the file, so in a chat with several tasks it is clear what the result belongs to.
Flowmark processes the recording on the service side. In the main scenario transcription can run locally; the result comes back to the chat, and temporary files aren't kept longer than processing requires.
The recognized text is also checked for the typical hallucinations — repeated phrases and stretches that models sometimes "invent" over long pauses — so they don't make it into the final text.
Voice messages, audio files, podcasts, interviews and video with speech. The "Audio to text" button appears in the menu when such a recording lands in the bot.
Yes. Transcribing video to text works the same way as for audio — the sound track is recognized, and you get text with timestamps.
The built-in transcription is handy for short voice notes. Flowmark is for when the recording is real work: an interview, a podcast, a video — with timestamps, speaker separation, formatting and the option to process the file itself right there.
Yes. Switching the output to paragraphs, or adding and removing timestamps, doesn't need a new transcription — the bot re-formats the already-recognized text.
Yes. Before you start, you turn on diarization — speaker separation. It works both line by line and in flowing paragraphs; timestamps are available alongside.
Your choice: plain text (TXT), a formatted DOCX or SRT subtitles for video and editing. The layout can be re-formatted — switched to paragraphs or have timestamps added — without re-transcribing.
Yes. By default the language is detected automatically, but it can be set explicitly — it helps on recordings with mixed speech, strong accents or rare terminology.
Enable the music mode: the voice is separated from the instrumental, and recognition runs on the clean vocal track. More on the transcribing recordings with music page.
Flowmark processes the recording on the service side; in the main scenario transcription can run locally. Temporary files aren't kept longer than processing requires.
There's a free plan, and the promo link opens 30 days of extended access to every tool.
